OUR SERVICE

Africa Language

Data.

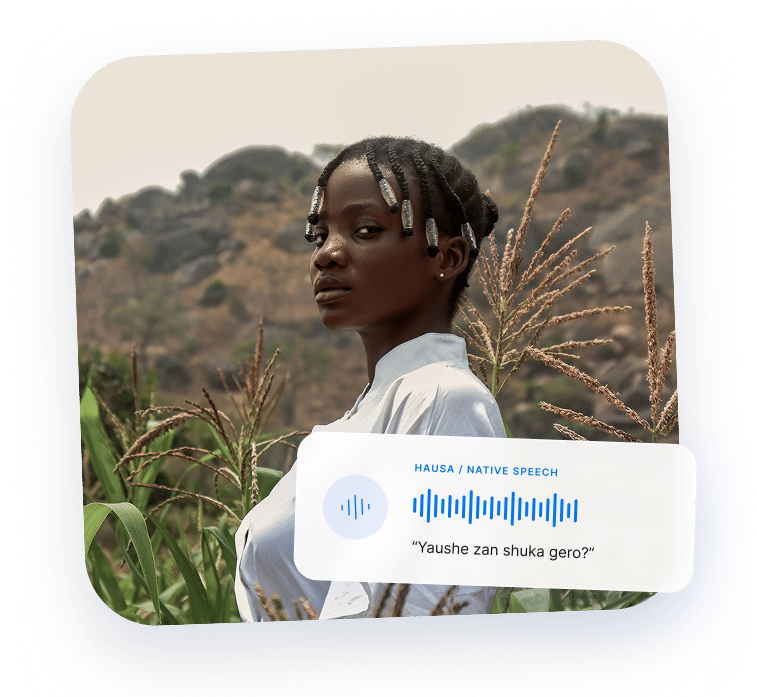
Think of a farmer in Kano who asks a voice assistant in Hausa when to plant millet and gets an answer she can use. That depends on a model trained and tested on Hausa speech and text prepared by people who speak it every day.

01

What it is

Clear, USEFUL, HUMAN

What is African Language Data?

African language data is speech, text and evaluation work in Hausa, Yoruba, Igbo, Bini (Edo), Urhobo, Itsekiri, Efik, Ibibio, Fulfulde and Twi. Native speakers prepare it so AI models can understand these languages, respond in them and be judged on how real people speak them.

01

Hausa

02

Yoruba

03

Igbo

04

Bini (Edo)

05

Urhobo

06

Itsekiri

07

Efik

08

Ibibio

09

Fulfulde

10

Twi

HOW WE WORK

How We Deliver High-Quality African Language Data

At Annotiq, native speakers handle every task, working from guidelines written in the target language.
01

Speech Transcription

Transcribing audio accurately, including tone-marked and code-switched speech.

02

Translation Checking

Checking each translation against its source, with reviewer notes on every correction.

03

Prompt and QA Writing

Writing question-answer pairs and prompts directly in the target language.

04

LLM Output Review

Reviewing and ranking model responses for accuracy, fluency and cultural fit.

05

Field Data Collection

Gathering speech and text data from speakers in their own communities.

06

Data Security & Compliance

Following strict confidentiality and consent practices for every speaker and file.

EVERY PROJECT

Each project starts with written guidelines in the target language and a second native-speaker review before delivery.

Get a Quote

We’d love to hear about your project and help you get started. Feel free to drop us a line.